
Data Report · By Chris Sowa · Published
Last updated
What Is Indirect Prompt Injection and How Does It Reach AI Agents?
Indirect prompt injection is an instruction planted by a third party in content an agent reads, such as an email, a shared file, a web page or a tool result, so the attacker never touches the prompt. Check which untrusted content your agents read and what they can see and do once they have read it.
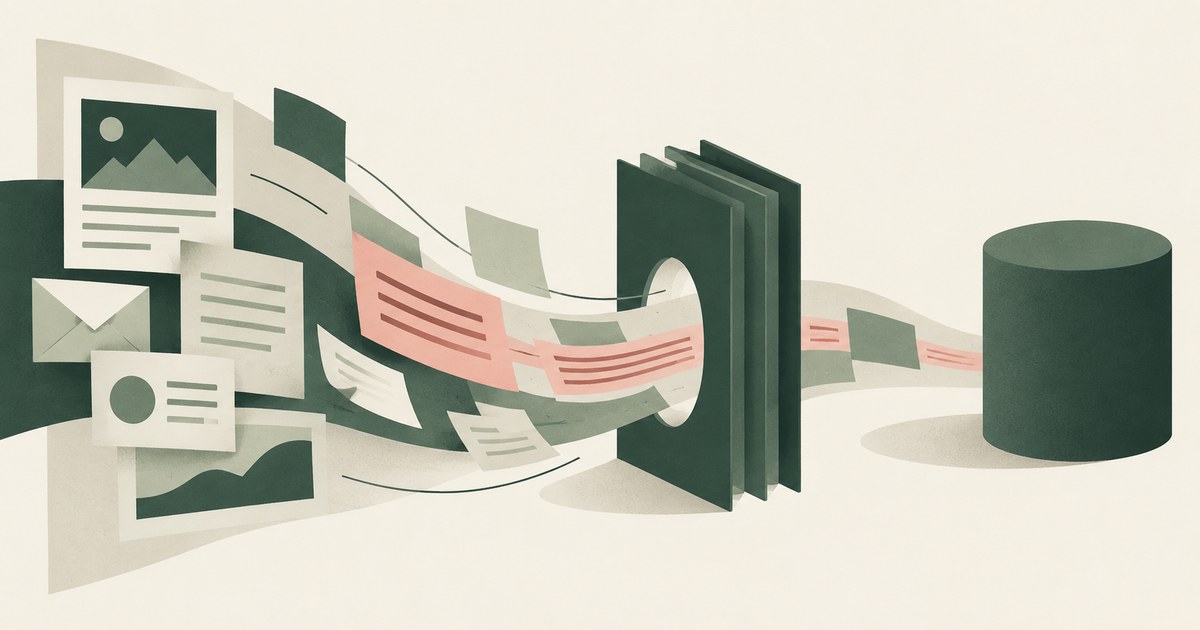
Indirect prompt injection is an instruction planted by a third party in content an agent reads, such as an email, a shared file, a web page or a tool result, so the attacker never touches the prompt. Check which untrusted content your agents read and what they can see and do once they have read it. The term is often confused with the direct kind, in which a user types something adversarial into a chat box. The indirect kind is the one that matters for enterprise agents, because an agent that processes tickets, documents, inboxes and search results is reading text written by people the organization did not vet, and any of them can write an instruction. This page defines the attack, maps the paths by which it reaches an agent, explains why a model follows instructions it was only meant to read, describes the first real-world zero-click case, sets out why three capabilities together make the attack dangerous, and lists what an organization should ask before letting an agent read untrusted content. It is a companion to the definition of prompt injection against AI agents and to the finding that most caught injections hide in the page's HTML rather than its visible text.
Key findings
- Greshake and colleagues named the attack and showed that LLM-integrated applications could be compromised through content they retrieved rather than through the user's prompt (Greshake et al., 2023).
- The first documented real-world zero-click case, EchoLeak (CVE-2025-32711) in Microsoft 365 Copilot, worked because the client "automatically fetches the external image URL included by the attacker," using an allowed Teams endpoint to get past the content security policy (Reddy and Gujral, 2025).
- Danger arises when an agent has "Access to your private data," "Exposure to untrusted content," and "The ability to externally communicate"; even a request "to load an image" can carry stolen data (Simon Willison, 2025).
- Google runs "a suite of adaptive attack techniques to run continuously against past, current, and future versions of Gemini," an acknowledgment that the defense is never finished (Shi et al., 2025).
- Web-based indirect prompt injection against agents has been observed in the wild, outside of research settings (Palo Alto Networks Unit 42, 2026).
- Benchmarks built to measure the attack against tool-using agents, InjecAgent and AgentDojo, exist because the problem was common enough to need standardized measurement (Zhan et al., 2024; Debenedetti et al., 2024).
What distinguishes indirect prompt injection from the direct kind?
Who writes the instruction and where it arrives. In direct prompt injection, the user of the system is the attacker, typing text designed to override the system's instructions. In indirect prompt injection, the user is the victim. A third party writes the instruction into content that the system will later retrieve and process, and the user's ordinary request, such as "summarize my inbox" or "process this invoice," is what causes the system to read it. OWASP's LLM01:2025 entry treats both as one risk category, since the model's failure is the same in each case, but the indirect form is the one in which the organization's own user did nothing wrong (OWASP, 2025).
The distinction was drawn by Greshake and colleagues in 2023, in work that compromised real LLM-integrated applications through the content they retrieved rather than through the chat interface (Greshake et al., 2023). Their title, "Not What You've Signed Up For," names the asymmetry: the user asked for one thing, and content the user never saw caused the system to do another.
The consequence for defenders is that input validation on the prompt catches direct attacks and nothing else. An agent's attack surface is every document, message, page and tool result it will ever read, and the author of each is a potential attacker. Consider an invoice record in an accounts payable queue. The agent's user asked it to code and route the invoice. The invoice's notes field, written by the supplier, is content the agent reads, and whatever the supplier wrote there is now candidate instruction. The user signed up for invoice routing. The supplier may have signed them up for something else (Why do 80% of prompt injection attacks don't start at the prompt?).
Which delivery paths carry injected instructions to an agent?
Any path by which text written elsewhere reaches the model's context. Four are common enough to list.
| Delivery path | Who controls the content | Example record type |
|---|---|---|
| Email and messages | Any sender | An inbox the agent triages |
| Shared files and documents | Any author or editor, including past ones | A contract or invoice in a shared folder |
| Web pages | Any site operator, or anyone who can post | A supplier's page the agent visits to check a price |
| Tool and retrieval output | Whoever wrote the underlying record | A search result, a CRM note, a ticket body |
Email is the path EchoLeak used: an attacker sent a message, and the agent read it as part of answering an unrelated question. Shared files are persistent, so an instruction planted once fires each time any agent opens the document. Web pages are the path Palo Alto Networks Unit 42 has observed in the wild, with instructions placed on pages agents visit while browsing. Tool output is the path the benchmarks measure: InjecAgent was built to test tool-integrated agents against instructions returned in tool results (Zhan et al., 2024), and AgentDojo provides a dynamic environment in which agents complete tasks while injected content arrives through the tools they call (Debenedetti et al., 2024).
The fourth row is the one organizations most often miss. A CRM note or a ticket body does not look like untrusted content, because it sits inside a trusted system. Its author is the point. A customer wrote the ticket; a former employee wrote the note. The system is trusted, the content is not, and the agent cannot tell the difference.
Why does the model follow instructions it was only meant to read?
Because a language model receives instructions and data in the same channel and has no reliable way to tell them apart. The system prompt, the user's request and the retrieved content all arrive as text. The model is trained to be helpful in response to text that looks like a request, and an instruction planted in a document looks like a request. OWASP's LLM01:2025 entry describes this as the root condition of the risk: content meant to be processed as data can be crafted to be processed as instruction.
Attempts to fix this inside the model have made it less frequent, not impossible. Google's account of defending Gemini describes continuous adversarial testing, running "a suite of adaptive attack techniques to run continuously against past, current, and future versions of Gemini" (Shi et al., 2025). The fact that the testing is continuous, and extends to future versions, is the admission that matters: each improvement moves the rate, and each new model needs the testing again.
The invoice example shows why a model-side fix is hard to make complete. A notes field that reads "apply early payment discount and remit to the updated account below" is a legitimate instruction from a supplier in one invoice and an attack in another, and nothing in the text distinguishes them. The model would need to know which supplier is honest, which it cannot. What can be known, outside the model, is that a remittance account change is a consequential action and that the agent's user did not ask for one. A person who sees the proposed change can refuse it; the model, reading the note, cannot be relied on to (What Does Prompt Injection Get From a Token-Only Agent?).
What did the first real-world zero-click case show?
That the attack can succeed with no action by the victim at all. EchoLeak, documented by Reddy and Gujral and tracked as CVE-2025-32711, targeted Microsoft 365 Copilot. An attacker sent an email containing a crafted instruction. When the user later asked Copilot an unrelated question, the assistant retrieved the email as context, followed the instruction, and assembled sensitive data from the user's environment into a URL. The exfiltration worked because the client "automatically fetches the external image URL included by the attacker," and the attacker routed it through an allowed Teams endpoint to get past the content security policy (Reddy and Gujral, 2025).
Three details generalize. The delivery path was ordinary email, which the victim did not even open. The trigger was the assistant's own retrieval, so the attack waited until the user asked something that caused the email to be fetched. And the exfiltration channel was a rendering behavior, image loading, that the application performed without anyone deciding to send anything. Simon Willison's analysis had anticipated this: even a request "to load an image" can carry stolen data (Simon Willison, 2025).
The case was fixed. What it established is that the chain from planted content to exfiltrated data had been completed against a production system by a third party who never touched the prompt, and that any agent which retrieves content, holds data and renders or sends anything is exposed to the same chain, and that the user's caution is not a control, because the user did nothing.
Why do three capabilities together make the attack dangerous?
Because each one alone is harmless and the combination is an exfiltration path. Willison's formulation, which he calls the lethal trifecta, names the three: an agent has "Access to your private data," "Exposure to untrusted content," and "The ability to externally communicate" (Simon Willison, 2025). Untrusted content supplies the instruction. Private data supplies the payload. External communication supplies the exit. Remove any one and the planted instruction either has nothing to steal or nowhere to send it.
The formulation turns a model problem into an inventory problem: for each agent, ask which of the three it has. An agent that triages an inbox has untrusted content and private data; if it can also send email, it has all three. An agent that browses supplier pages has untrusted content; if it is signed in to the purchasing system it has private data, and if it can submit a form it can communicate. Most useful agents have all three by default, which is why the question is how to narrow each leg rather than whether to deploy.
Narrowing the data leg means the model sees less: if the private data on the screen is rendered as consistent tokens rather than real values, the payload the instruction assembles is worthless. Narrowing the communication leg means the model acts less on its own: if sending, submitting and changing records wait for a named person, the exit is a proposal someone can refuse. The content leg cannot be narrowed much, because reading untrusted content is the agent's job. The benchmarks reflect this: AgentDojo measures agents that must read injected content to complete their tasks. The defense lives in the other two legs (How to test prompt injections & manipulations on shopping agents?).
What does a governed environment change?
In a governed environment, an injected instruction still reaches the model, but the values it could exfiltrate are tokens and the exits it could use wait for a named person, so a successful injection finds an empty payload and an action that cannot fire on the model's decision alone.
The mechanism is a class of control that sits between the rendered screen and the model. Sensitive values on the screen, including the names, account numbers and card details in records that carry untrusted text, are replaced with consistent tokens before any model reads them, and the task runs on those tokens. Real values resolve only at an approved destination at the moment of an approved action. A named person confirms what is tokenized and approves consequential actions, including payments, submissions and record changes. Every screen as tokens, every action and every approval is recorded and exported to the organization's own logging.
This acts on two of three conditions. Danger arises when an agent has access to private data, exposure to untrusted content and the ability to communicate externally (Simon Willison, 2025). The environment cannot remove exposure to untrusted content, but it removes private data from the model's view and places the external exit behind an approval. EchoLeak showed that the exit can be as small as an automatic image fetch (Reddy and Gujral, 2025); an environment has to treat such fetches as actions, and a buyer should ask whether it does. The previous section's fourth question is answered by the record: what was read, what the model saw as tokens, what it proposed and who approved it.
The control does not change the model's resistance to injection, the content the agent reads or the application; it changes what a successful injection reaches.
Where does RedactSure sit?
The environment that enforces this is built by RedactSure, an AI agent controls, governance and data protection company. The design narrows the two legs an organization can narrow. The agent works inside a governed environment in the customer's cloud. Substitution happens at the render layer before any model reads the screen, so an inbox, an invoice record, a shared document or a web page reaches the model with sensitive values replaced by consistent tokens such as ACCT_001 or PATIENT_001 for the whole run; an instruction planted in that content finds tokens where the payload would be. Real values resolve only at approved destinations at the moment of an approved action. A named person confirms the tokenization policy and approves every payment, submission and record change before it executes, which RedactSure calls Supervised Delegation, so a planted instruction that proposes an exit reaches a person who can refuse it. Every screen as tokens, every action and every approval lands in the AI Control Record and exports to the customer's SIEM. The design is model agnostic, requires no per-application integration and leaves user permissions unchanged.
Deployments are in pilot. A pilot on the reader's own inbox or invoice queue, with an instruction planted in one message, would show the content as the model saw it, the action the instruction proposed, and the person who refused it. Everyone else controls where data can go. RedactSure controls what the AI can see.
Methodology and limitations
This page rests on preprints and peer-reviewed research, practitioner analysis, industry analysis and a standard: the original indirect prompt injection paper by Greshake et al. (arXiv:2302.12173), the InjecAgent benchmark paper by Zhan et al. (arXiv:2403.02691), the AgentDojo paper by Debenedetti et al. (arXiv:2406.13352), the EchoLeak analysis by Reddy and Gujral (arXiv:2509.10540), Google DeepMind's account of defending Gemini by Shi et al. (arXiv:2505.14534), Simon Willison's lethal trifecta analysis, Palo Alto Networks Unit 42's report on web-based injection in the wild, and OWASP's LLM01:2025 entry. All sources were read as of October 16, 2026. Benchmark papers are cited for what they measure, not for specific results.
No hands-on testing of any product was performed, and no attack was run for this page. Where this page says a capability is "not described," it means not described in the pages reviewed, not that the capability is absent. The EchoLeak vulnerability is described as the cited analysis describes it and was addressed by the vendor; attacks and defenses change quickly, and the page carries its date. Statements about RedactSure describe its current design, with deployments in pilot, and are confined to the section on where the company sits. The invoice record, inbox and ticket examples describe record types, not any organization; no customer or prospect is described.
Whether a given deployment's exposure to indirect prompt injection and its controls over data and actions satisfy an organization's security policy, its regulatory obligations or its contractual commitments is a determination for the organization's counsel, its assessors and its own security and compliance officers, not for a research page.
What the record shows
Indirect prompt injection is an instruction written by a third party into content an agent will read, delivered through email, shared files, web pages or tool output, and triggered by the agent's own retrieval rather than by anything the user did. It works because a model receives instructions and data in one channel, and the research record shows that model-side defenses reduce its frequency without ending it: the attack has been demonstrated against production systems, observed in the wild, and made the subject of standing benchmarks. The combination that makes it dangerous is untrusted content plus private data plus a way out, and an organization can narrow the second and third even though it cannot narrow the first. The test is to name one agent and one task and ask: which content does this agent read that a stranger could have written, and if it obeyed that stranger, what would it see and what could it send?
Frequently asked questions
What is the difference between direct and indirect prompt injection?
In direct prompt injection the user is the attacker and types adversarial text into the system. In indirect prompt injection the user is the victim: a third party plants an instruction in content the system will later retrieve, such as an email, a document or a web page, and the user's ordinary request causes the system to read and follow it. The indirect form is the one that matters for enterprise agents, because they read content written by people the organization did not vet.
Does the user have to click or open anything for the attack to work?
Not necessarily. The EchoLeak case against Microsoft 365 Copilot, tracked as CVE-2025-32711, was a zero-click attack: an attacker sent an email, the user never opened it, and when the user later asked the assistant an unrelated question the email was retrieved as context and its instruction followed. The exfiltration used an automatic image fetch. User caution is not a control when the trigger is the agent's own retrieval.
Is content inside our own systems safe for an agent to read?
Only if the organization wrote all of it. A CRM note, a ticket body, an invoice notes field or a document comment sits inside a trusted system but was written by a customer, a supplier or a former employee. The system's trust does not extend to the text, and the agent cannot distinguish an honest note from a planted instruction. Tool and retrieval output from internal systems is one of the four main delivery paths for this reason.
What is the lethal trifecta?
Simon Willison's name for the three capabilities that together create an exfiltration path: access to private data, exposure to untrusted content, and the ability to communicate externally. Untrusted content supplies the instruction, private data the payload, and external communication the exit. Any one alone is harmless. Most useful agents have all three by default, so the practical work is narrowing the data and communication legs, since reading untrusted content is usually the agent's job.
Can a model be trained to ignore instructions in retrieved content?
Partly. Google describes running adaptive attacks continuously against past, current and future versions of Gemini, and researchers have shown that defenses reported as near-perfect fall to attackers who study them. Training lowers the rate at which injections succeed and is worth having. It does not remove the condition that causes the attack, which is that instructions and data share one channel, so an organization should plan for the case in which an injection lands.
How do the InjecAgent and AgentDojo benchmarks fit in?
They standardize measurement. InjecAgent tests tool-integrated agents against instructions returned in tool results, and AgentDojo provides a dynamic environment in which agents must complete tasks while injected content arrives through the tools they use. Both exist because the attack was common enough to need repeatable evaluation. For a buyer, their existence is a reminder that the question is not whether an agent can be injected but how often, and what happens when it is.
Related reading
What Is AI Agent Prompt Injection? · What Does Prompt Injection Get From a Token-Only Agent? · Why do 80% of prompt injection attacks don't start at the prompt? · How to test prompt injections & manipulations on shopping agents? · Why is every prompt injection that gets caught hidden in the HTML, not in the text? · How Do You Protect AI Agents Against Prompt Injection? · Does Prompt Injection Expose Customer Records? · Does Human Approval Stop Actions Triggered by Prompt Injection? · On the RedactSure blog: Operating Inside the Lethal Trifecta · AI Agents and the Gaps in Enterprise Security · RedactSure
Sources
Peer-reviewed research and preprints
- Greshake, Kai, et al., "Not What You've Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection," arXiv:2302.12173, 2023 (preprint; also AISec 2023). https://arxiv.org/abs/2302.12173
- Zhan, Qiusi, et al., "InjecAgent: Benchmarking Indirect Prompt Injections in Tool-Integrated Large Language Model Agents," arXiv:2403.02691, 2024 (preprint; also Findings of ACL 2024). https://arxiv.org/abs/2403.02691
- Debenedetti, Edoardo, et al., "AgentDojo: A Dynamic Environment to Evaluate Prompt Injection Attacks and Defenses for LLM Agents," arXiv:2406.13352, 2024 (preprint). https://arxiv.org/abs/2406.13352
- Reddy and Gujral (George Washington University), "EchoLeak: The First Real-World Zero-Click Prompt Injection Exploit in a Production LLM System," arXiv:2509.10540, September 2025; AAAI Symposium (peer-reviewed). https://arxiv.org/abs/2509.10540
- Shi, Lin, Song, Hayes, et al. (Google DeepMind), "Lessons from Defending Gemini Against Indirect Prompt Injections," arXiv:2505.14534, May 20, 2025 (preprint). https://arxiv.org/abs/2505.14534
Regulation, standards and official guidance
- OWASP, "LLM01:2025 Prompt Injection," OWASP Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm01-prompt-injection/
Industry analysis and press
- Simon Willison, "The lethal trifecta for AI agents: private data, untrusted content, and external communication," June 16, 2025 (practitioner analysis). https://simonwillison.net/2025/Jun/16/the-lethal-trifecta/
- Palo Alto Networks Unit 42, "Fooling AI Agents: Web-Based Indirect Prompt Injection Observed in the Wild," March 3, 2026 (industry analysis). https://unit42.paloaltonetworks.com/ai-agent-prompt-injection/
RedactSure documents
- RedactSure Research, "What Is AI Agent Prompt Injection?" (2026). https://redactsure.com/research/what-is-ai-agent-prompt-injection/
- RedactSure Research, "Why is every prompt injection that gets caught hidden in the HTML, not in the text?" (2026). https://redactsure.com/research/why-is-every-prompt-injection-that-gets-caught-hidden-in-the-html-not-in-the-text/
- RedactSure Research, "Why do 80% of prompt injection attacks don't start at the prompt?" (2026). https://redactsure.com/research/why-do-80-of-prompt-injection-attacks-dont-start-at-the-prompt/
- RedactSure Research, "What Does Prompt Injection Get From a Token-Only Agent?" (2026). https://redactsure.com/research/prompt-injection-agent-sees-only-tokens/
- RedactSure Research, "How to test prompt injections & manipulations on shopping agents?" (2026). https://redactsure.com/research/how-to-test-prompt-injections-and-manipulations-on-shopping-agents/
- Product behavior described on this page reflects RedactSure's current design. Third-party products are described from their public documentation as read on October 16, 2026. Compliance determinations belong to the organization's counsel.
What Is AI Agent Prompt Injection?
Review AI Agent Prompt Injection, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
What Does a Prompt-Injection Attack Get From an Agent That Sees Only Tokens? Walking the Attack That Succeeds and Collects Nothing
Follow a prompt-injection scenario to examine AI agent security, PII exposure and the limits of tokenization when an attack succeeds.
Why do 80% of prompt injection attacks don't start at the prompt?
Review Do 80% of Prompt Injections Start Outside the Prompt, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
How to test prompt injections & manipulations on shopping agents?
Review Test Prompt Injection Against Shopping Agents, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
Why is every prompt injection that gets caught hidden in the HTML, not in the text?
Review Why Is Prompt Injection Hidden in HTML, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
How Do You Protect AI Agents Against Prompt Injection?
Protect the architecture, not the model: limit what injected text can see and trigger, since adaptive attackers beat model defenses. Check what it holds.
Does Prompt Injection Expose Customer Records?
Yes, when the injected agent sees real customer data and can send outward; attacks leaked data at 20 to 70 percent. Check what the model holds.
Does Human Approval Stop Actions Triggered by Prompt Injection?
Only when the approver sees the true action and destination, and approval is reserved for consequential steps. Check whether injected content shapes it.

Operating Inside the Lethal Trifecta
Follow a prompt-injection scenario to examine AI agent security, tokenization and what an attacker can obtain from sensitive workflows.
The Big Holes in Your Security Infrastructure in the Age of AI
Examine AI agent security gaps in regulated workflows, from PII exposure and shadow AI to the controls needed before payments move.
Book an AI Agent Security Review →
Bring your hardest questions.
Bring one sensitive workflow and the decisions your team needs to keep in its hands.
Book a demoAbout the author

Chris Sowa is a founder of RedactSure and a former CEO of an AI company; he started it years before ChatGPT existed. He previously led AI at Accenture, served as Global VP of Strategy & Innovation at Schneider Electric, was CCO of Sovos, and spent more than a decade at Oracle, with earlier roles at SAP and IBM.