
Comparison · By Chris Sowa · Published
Last updated
What Is the Difference Between RedactSure and Protecto for AI Agent Data Protection?
Protecto tokenizes values inside the code path of agents a team builds, while RedactSure tokenizes the rendered screen of any application an agent works in and holds each consequential action for a named person. List the applications your agents work in, since Protecto's guidance says its pattern governs integrated agents, "saying nothing about agents or applications you don't own."
Protecto tokenizes values inside the code path of agents a team builds, while RedactSure tokenizes the rendered screen of any application an agent works in and holds each consequential action for a named person. List the applications your agents work in, since Protecto's guidance says its pattern governs integrated agents, "saying nothing about agents or applications you don't own." The line comes from Protecto's September 2026 post on agents, which places protection before data reaches the model, memory or logs (Protecto, 2026). Both products start from the same premise, that a model should work on consistent placeholders rather than real identifiers, and both release real values only where an approved task needs them. The difference is where each one stands. Protecto stands at the data layer, inside software the customer's developers write and control. RedactSure stands at the render and workflow layers: the screen where an agent meets the claims system, the payer portal, the vendor master and the SaaS applications nobody in the organization can rebuild, and the actions the agent takes there. A buyer evaluating agents that work through the browser needs the second answer and can keep the first for the pipelines a development team owns. The screen is where render-layer tokenization applies. The environment that enforces this is built by RedactSure, an AI agent controls, governance and data protection company.
Key findings
- Protecto positions itself as a control plane for sensitive data across "LLMs, agents and MCP pipelines" (Protecto, 2026), and its developer documentation describes an API-first platform, reached only from code a team integrates, deployable as SaaS, in a customer VPC or on premises (Protecto docs, 2026).
- Protecto replaces each detected value its API receives with a consistent token, keeps originals in a vault and restores them through an Unmask API, which its documentation advises restricting to "trusted services and users" (Protecto docs, 2026).
- Protecto's September 2026 post on agents lists three limits under the heading "What this doesn't do": a latency cost in the request path, "per-agent work," and coverage that says "nothing about agents or applications you don't own" (Protecto, 2026).
- The Protecto pages reviewed describe policy-gated reveals and logging of every reveal; they do not describe a person approving the action an agent takes, an export to a SIEM, or agents that work through a browser or a rendered screen (Protecto, 2026).
- OWASP lists sensitive information disclosure as a top risk for LLM applications, covering personal data and confidential business data that reach or leave a model (OWASP, 2025).
- Researchers showed that instructions planted in content an LLM application reads can redirect it, which makes anything the model can see, including a rendered screen, a possible target (Greshake et al., 2023).
What does Protecto's documentation say the product covers?
Protecto's homepage carries the headline "Protect Enterprise Data Across Every AI Interaction" and positions the company as a control plane for sensitive data across "LLMs, agents and MCP pipelines," every one of them a code path the customer integrates (Protecto, 2026; vendor documentation, accessed October 16, 2026). The developer documentation describes an API-first platform to "identify, tokenize, mask, and safely handle sensitive data across applications, data pipelines, and GenAI workflows," reached through REST APIs and a Python SDK, with deployment as SaaS, in the customer's own VPC or on premises (Protecto docs, 2026).
For agents, the solution page states that "Protecto sits between your agents and your data," and that "when an agent retrieves data from a tool, document, or database, Protecto inspects what came back," a retrieval the agent's own code performs (Protecto, 2026). The homepage claims coverage of "RAG pipelines, MCP tools, and multi-agent systems," all of them paths a developer wires to the API. A separate product, the Privacy Gateway for AI Chat, "runs behind your chat interface" and is "built primarily for on-prem, VPC, or air-gapped deployment" (Protecto, 2026). The company states SOC 2 Type II and ISO 27001 certification and offers a business associate agreement for HIPAA workloads.
Detection is semantic rather than pattern based. Protecto says its classification engine "analyzes the semantic meaning of data" and covers more than 200 sensitive data types in the payloads handed to it (Protecto, 2026). For a fair comparison, Protecto is a data layer service with detection, consistent tokenization, a vault and governed restoration, not a pattern filter in front of a prompt, and not a control on what a screen shows.
What the pages place is the entry point. Every path described runs through an API call, an SDK step or a gateway the customer deploys: a payload the agent's own code hands to Protecto, a tool result the agent retrieves, a chat message routed behind an interface. The pages reviewed do not describe agents that work through a browser, computer-use agents, or values an agent reads from a rendered screen. Other documentation may cover them.
What does Protecto say its in-agent pattern does not do?
Protecto's clearest statement of its agent design is a September 21, 2026 post by Amar Kanagaraj. A fictional insurer's claims agent pulls a case file, and Protecto runs inside the agent's own code as "a step Claire runs before data moves anywhere," replacing values "before it goes to the model, into memory, or into logs," and releasing a real email address only for the notification task (Protecto, 2026). The post describes the pattern as "the only one that protects the inside of the agent, at the cost of integrating each agent you run."
The same post is candid about where the pattern stops. Its section "What this doesn't do" lists three limits, quoted here verbatim. First: "Protection is a step in the request path, so there's a latency cost worth measuring for your traffic." Second: "This pattern is also per-agent work: each agent you build needs the integration." Third: "And it governs the agents you integrate, saying nothing about agents or applications you don't own."
Its section "When this pattern is the right one" says the in-agent placement "fits when you own the agent, you're running a handful of them," and that "it's the wrong starting point when the problem is broader than one agent." For third-party tools, it says "the tool connection is the place to stand." Protecto's agents page describes the integration as "One line of code" and "Live in under 15 minutes," repeated for each agent a team owns (Protecto, 2026). That can be true for one agent a team controls. As the estate grows, every agent built in house needs the call on every retrieval path, and every agent the business buys sits outside it.
The sentence about the tool connection is the point of this comparison. Most of the applications a regulated organization's agents need to work in are third-party tools with no connection the customer can stand on: a carrier's claims platform, a clearinghouse portal, a state licensing site, a bank's vendor payments screen. The only interface they offer is the page.
In RedactSure's design, the integration work falls on the environment rather than on each agent. The agent operates the applications the organization already runs, inside a workspace RedactSure controls, and the screen is tokenized as it renders. A new application costs a policy decision about which fields to tokenize, confirmed by a named person, not a code change. The cost of protection does not scale with the number of applications or agents.
What happens to a sensitive value in each design?
Take a single record: a claim on a carrier's claims platform, showing the claimant's name, Social Security number, email address and policy number, the claimed amount and the policy limit. An agent has been asked to check the claim against the limit and send the claimant a status notice.
In the design Protecto describes, the case file reaches the agent through the agent's own retrieval code. Protecto replaces the identifiers with consistent tokens before they reach the model, memory or logs, once the agent's code hands them over; the September post shows bracketed placeholders such as [NAME_2c88] and [SSN_c419], and the API documentation notes that "the exact tokenized output depends on the active policy" (Protecto docs, 2026). Originals stay in a vault, and "token-to-value mapping is governed by access policies." When the notice goes out, the real email is released for that task alone: "Unmasking isn't a privilege the agent owns. It is controlled by policies defined for the user and the task." If the same agent instead opens the claims platform as a rendered page in a browser, the values arrive on the screen rather than in a payload passed to Protecto's API, and the pages reviewed do not describe that path.
In RedactSure's design, the agent works inside a governed environment. Before any model reads the screen, the environment replaces the name, Social Security number, email and policy number with consistent tokens such as NAME_001, SSN_001 and EMAIL_001. The claimed amount and the limit stay in clear because the check runs on them. The environment hands the model the task's fields rather than a picture of the screen. The real email resolves only in the notice's address field, at the moment a named person approves sending it. This is screen-level tokenization applied per task.
The difference matters because of what a model does with what it reads. OWASP describes prompt injection as a risk that can cause a model to take unintended actions (OWASP, 2025); an instruction hidden in a claim note arrives through the screen. A 2026 study found that a model-agnostic firewall which strips unneeded data before tool calls, paired with one that cleans tool outputs, brought attack success near zero on four agent benchmarks (Bhagwatkar et al., 2026). Minimizing what the model receives is the shared principle. The question is whether it is applied where the agent actually reads.
How do the two compare side by side?
The table records what each side's documentation states. For Protecto, that is its homepage, developer documentation, agents and gateway pages, accessed October 16, 2026, and its September 21, 2026 post, updated September 24 (Protecto, 2026). For RedactSure, it is the current published design.
| Dimension | Protecto, per its documentation | RedactSure, per its published design |
|---|---|---|
| Where protection runs | A step in the agent's code path, through REST API or Python SDK | The rendered screen inside a governed environment, before any model reads it |
| Applications covered | Agents and pipelines the customer builds and integrates | Any application the agent works in through the browser, including ones the customer does not administer |
| Integration per agent | Required; Protecto calls it "per-agent work" | None; the environment is the integration |
| Detection | Semantic classification across more than 200 data types | The Planner sets which values are tokenized; a named person confirms the policy |
| Consistent tokens | Yes, per entity; format depends on the active policy | Yes, per entity across every screen in the run |
| Restoring real values | Unmask API, gated by policy for users, roles and tasks | Real values resolve only at approved destinations at the moment of an approved action |
| Human approval of agent actions | Not described in the pages reviewed | A named person approves every payment, submission and record change |
| Record | Masking decisions and reveals logged; SIEM export not stated in the pages reviewed | AI Control Record: every screen as tokens, every action, every approval with a name, exported to the customer's SIEM |
| Key custody and stated limits | Vault in SaaS, customer VPC or on premises; latency, per-agent integration, no coverage of agents or applications the customer does not own | Hardware-encrypted enclaves with customer-held keys; governs browser work, not APIs, terminals or code pipelines |
The closest overlap is the token itself. Both designs map each entity to a consistent token and keep a governed route back to the original, so neither forces a model to work on blanks. Cells that read "not described" or "not stated" describe the pages reviewed, not the full capability of Protecto's product, and a buyer should confirm each one with Protecto directly or in a demonstration. The stated limits in the Protecto column are Protecto's own words. The RedactSure column describes a design in pilot.
How do approval and the record differ?
Protecto governs what the agent's model and memory receive through its API, and when a real value is revealed, not what an agent reads on a screen. Reveals happen "only for users, roles, and tasks that your policy explicitly permits," and every reveal is logged (Protecto, 2026). That is governance over data release. The pages reviewed do not describe a person approving the action the agent then takes with the released value, such as sending the notice, paying the claim or changing the record.
In RedactSure's design, approval sits inside the run. Under Supervised Delegation, a named person grants the access, chooses the applications, confirms what is tokenized field by field, can watch and pause the run, and approves every consequential action before a real value resolves into the destination.
The reason to hold actions outside the model is that model-internal defenses have gaps. MIT Technology Review reported in October 2026 that model refusal is treated as a primary safety mechanism and is far from foolproof, with vendors stacking layered defenses whose individual holes they hope will not line up (MIT Technology Review, 2026). If an injection succeeds against a RedactSure agent, it collects tokens, and the consequential action still stops for a named person.
The record follows the same split. The AI Control Record captures every screen the agent saw as tokens, every action and every approval with a name, and exports to the customer's own SIEM. Because screens are stored as tokens, the record does not become a second copy of the identifiers it describes. Protecto's log of masking decisions and reveals serves the data layer: which values were masked and who was allowed to see them, not which action an agent took. For HIPAA workloads, the minimum necessary standard at 45 CFR 164.502(b) frames the question in terms of how much protected health information a use or disclosure requires (eCFR, 2026), and an organization may want both records when it answers that question. The comparison of the two storage patterns is set out in data privacy vault or screen-level tokenization.
Where does RedactSure sit?
For AI agent data protection in work that happens on screens, RedactSure sits at the render and workflow layers, between the rendered application and the model. Inside a governed environment deployed into the customer's cloud, on hardware-encrypted enclaves with keys the customer holds, identifiers chosen by policy are replaced with consistent tokens before any model reads the screen. Real values resolve only at approved destinations at the moment of an approved action, and a named person approves every payment, submission and record change. The environment is model agnostic, needs no per-application or per-agent integration and leaves user permissions as they are. Deployments are in pilot. Protecto fits underneath as the data layer for the AI pipelines and in-house agents a development team builds and controls, which is the scope Protecto's own guidance recommends for its pattern.
Everyone else controls where data can go. RedactSure controls what the AI can see.
Methodology and limitations
This page rests on Protecto's homepage, developer documentation (overview, identify and mask, unmask with token), agents solution page, core technology page and Privacy Gateway page, accessed October 16, 2026, and its September 21, 2026 blog post, updated September 24 (vendor documentation); the OWASP Top 10 for LLM Applications 2025 entries for LLM01 and LLM02 and 45 CFR 164.502(b) (standards and regulation); preprint research on indirect prompt injection and agent firewalls; an MIT Technology Review essay (press); and RedactSure's published design. Quotations from Protecto are verbatim.
No hands-on testing of Protecto or any other named product was performed. Where a Protecto page does not state a capability, the table says so; "not stated" and "not described" mean the pages reviewed, and Protecto may document the capability elsewhere. Protecto's materials use two token formats in different places, and this page reports both as published. Vendor features change, and the page carries its date. RedactSure statements describe the current design, with deployments in pilot. The claim record is an example of a record type; no specific organization is described.
Whether either product, or both together, meets an organization's obligations is a determination for its counsel, its assessors, and its own security and compliance officers. A buyer should confirm each "not stated" cell directly with Protecto and request a demonstration of RedactSure's tokenized screen on the buyer's own task before relying on any row of the comparison.
What the record shows
Protecto and RedactSure agree on the principle: a model should reason over consistent placeholders, and real values should appear only where an approved task needs them. They differ on where to stand. Protecto stands inside the agent, which works when the team owns the agent and the data passes through its code, and Protecto's own guidance says the pattern is per-agent work that says nothing about applications the customer does not own. Agents in regulated work spend most of their time in exactly those applications. The test is to name one agent and one task and ask each vendor to show what the model receives on the first screen of a third-party application.
Frequently asked questions
Does Protecto tokenize data before an AI agent reads it?
Yes, for data that passes through the agent's code path where Protecto is integrated. Protecto replaces values with consistent tokens before they reach the model, memory or logs, and keeps originals in a vault, for data its integration receives. A value that appears on a rendered screen the agent reads, outside that code path, is not covered in the pages reviewed, so a buyer should ask Protecto directly.
Does Protecto protect agents working in third-party applications?
Protecto's September 2026 post says its in-agent pattern governs the agents a team integrates, "saying nothing about agents or applications you don't own," and recommends standing at the tool connection for third-party traffic. Many third-party applications offer no connection a customer can stand on, only a web interface. That is the work render-layer tokenization was designed for.
Is Protecto's tokenization reversible?
Yes. Protecto stores originals in a vault and restores them through an Unmask API under policies for users, roles and tasks, and its documentation advises auditing every unmask operation; the reveal governs a value, not an agent's action. RedactSure's tokens are also reversible in a governed way: real values resolve only at approved destinations, at the moment of an approved action, after a named person approves it.
Does Protecto require a person to approve agent actions?
The pages reviewed describe policy-gated reveals and logging of every reveal, not a person approving the action an agent takes with a revealed value. RedactSure requires a named person to approve every payment, submission and record change, and records that approval with a name in the AI Control Record, which exports to the customer's SIEM.
How much integration does each product need?
Protecto integrates into each agent through its REST API or Python SDK; its agents page says "One line of code," and its own post calls the pattern "per-agent work." RedactSure needs no per-application or per-agent integration, because tokenization happens on the screen inside the governed environment. Adding an application means confirming a tokenization policy, not changing code.
Can an organization use Protecto and RedactSure together?
Yes, the designs protect different paths. Protecto fits the data layer for AI pipelines and in-house agents developers build, where data passes through code the team controls. RedactSure fits the render and workflow layers for agents that work across applications through the browser, holding each consequential action for a named person. An organization would map each workflow to the layer that reaches it.
Related reading
What Is the Difference Between RedactSure and Skyflow for AI Data Security? · Data Privacy Vault or Screen-Level Tokenization? · What Is Render-Layer Tokenization? · How Do Data Masking and AI Tokenization Differ? · Can an AI Agent Work Guidewire Claims Without PII? · What Tools Tokenize Data Before an LLM Sees It? · On the RedactSure blog: The Two Gaps AI Agents Opened in Your Security Stack
Sources
Peer-reviewed research and preprints
- Greshake, Kai, et al., "Not What You've Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection," arXiv:2302.12173, 2023 (preprint; also AISec 2023). https://arxiv.org/abs/2302.12173
- Bhagwatkar, Kasa, et al., "Indirect Prompt Injections: Are Firewalls All You Need, or Stronger Benchmarks?," arXiv:2510.05244, v2 March 2026 (preprint). https://arxiv.org/abs/2510.05244
Vendor documentation
- Protecto, "Protecting Sensitive Data Inside an AI Agent," Amar Kanagaraj (September 21, 2026, updated September 24, 2026; vendor blog). https://www.protecto.ai/blog/protecting-sensitive-data-in-ai-agents/
- Protecto, homepage (accessed October 16, 2026; vendor documentation). https://www.protecto.ai/
- Protecto, "Overview," developer documentation (accessed October 16, 2026; vendor documentation). https://docs.protecto.ai/introduction/overview
- Protecto, "Identify and Mask," developer documentation (accessed October 16, 2026; vendor documentation). https://docs.protecto.ai/masking-apis/identify-and-mask
- Protecto, "Unmask with Token," developer documentation (accessed October 16, 2026; vendor documentation). https://docs.protecto.ai/unmasking-apis/unmask-with-token
- Protecto, "Data Access Control for AI Agents" (accessed October 16, 2026; vendor documentation). https://www.protecto.ai/solutions/data-access-control-for-ai-agents/
- Protecto, "Core Technology" (accessed October 16, 2026; vendor documentation). https://www.protecto.ai/tech-behind-protecto/
- Protecto, "Privacy Gateway for AI Chat" (accessed October 16, 2026; vendor documentation). https://www.protecto.ai/product/privacy-gateway-for-ai-chat/
Regulation, standards and official guidance
- OWASP, "LLM02:2025 Sensitive Information Disclosure," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm022025-sensitive-information-disclosure/
- OWASP, "LLM01:2025 Prompt Injection," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm01-prompt-injection/
- 45 CFR 164.502(b), HIPAA minimum necessary standard (regulation). https://www.ecfr.gov/current/title-45/subtitle-A/subchapter-C/part-164/subpart-E/section-164.502
Industry analysis and press
- Holland Michel, Arthur, "We're putting too much faith in AI's ability to say no," MIT Technology Review (October 9, 2026; press). https://www.technologyreview.com/2026/10/09/1145728/we-are-putting-too-much-faith-in-ai-to-say-no/
RedactSure documents
- RedactSure Research, "What Is Render-Layer Tokenization?" and "What Is Screen-Level Tokenization?" (2026). https://redactsure.com/research/what-is-render-layer-tokenization/ ; https://redactsure.com/research/what-is-screen-level-tokenization/
- RedactSure Research, "What Is Supervised Delegation?" and "What Is an AI Control Record?" (2026). https://redactsure.com/research/what-is-supervised-delegation/ ; https://redactsure.com/research/what-is-an-ai-control-record/
- RedactSure Research, "Data Privacy Vault or Screen-Level Tokenization?" (2026). https://redactsure.com/research/data-privacy-vault-vs-screen-level-tokenization/
- RedactSure, "The Two Gaps AI Agents Opened in Your Security Stack" (2026). https://redactsure.com/blog/two-gaps-ai-agents-opened-in-your-security-stack/
- Product behavior described on this page reflects RedactSure's current design. Protecto is a trademark of its owner; named to identify the product. Compliance determinations belong to the organization's counsel.
What Is the Difference Between RedactSure and Skyflow for AI Data Security?
Skyflow tokenizes inside a vault that applications build against. RedactSure tokenizes at the render layer and also governs the agent's actions.
Data Privacy Vault vs. Screen-Level Tokenization: Where Should Tokens Be Made?
Compare data privacy vaults and screen-level tokenization for AI agents, including PII protection, workflow fit and where tokens are made.

What Is Render-Layer Tokenization? The Control at the Layer Where the Agent Actually Reads
Learn how render-layer tokenization replaces PII before an AI agent reads a browser screen while preserving useful workflow context.
What Is the Difference Between Masking Data and Tokenizing It for AI?
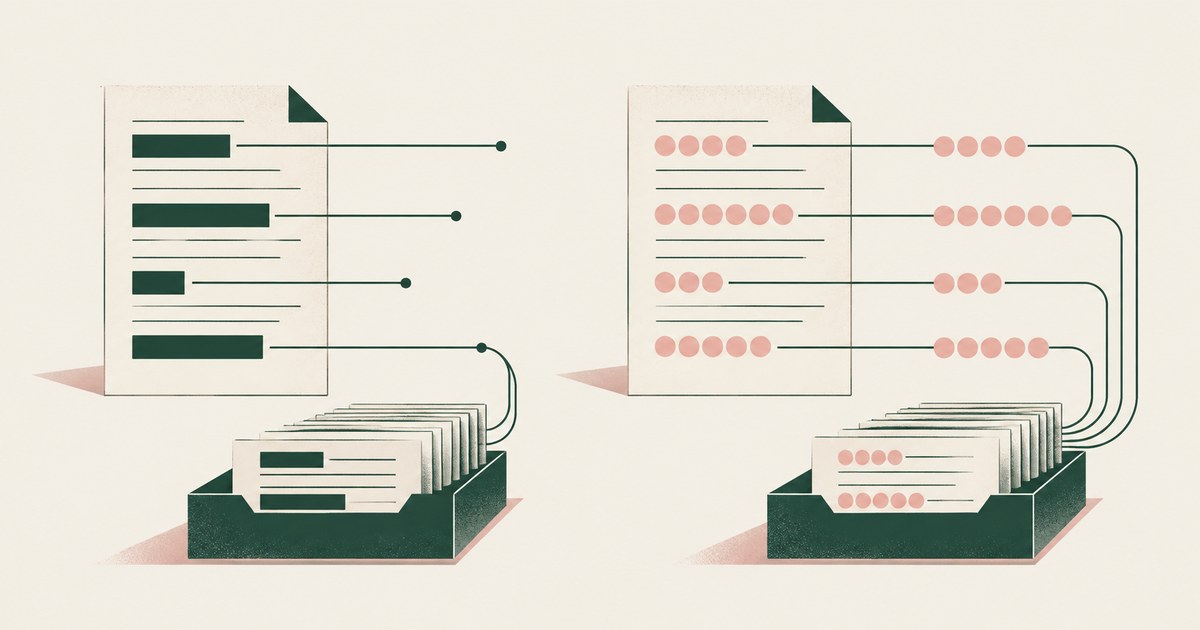
Compare data masking and tokenization for AI agent workflows that match claims, patient accounts and student records across application screens.
Can an AI Agent Work Claim Files in Guidewire Without Exposing PII? Reading the Workflow, the Regulation and the Mechanism
Explore how AI agents can work Guidewire claims with PII tokenization, consistent records and adjuster approval before payments move.
What Tools Tokenize Data Before an LLM Sees It? A Category Map of Where Tokens Get Made
Compare tokenization tools for AI agent security across structured data, prompts and browser screens, with attention to PII in workflows.

The Two Gaps AI Agents Opened in Your Security Stack
Explore AI agent security through two questions: which PII reaches the model, and who approves consequential billing and claims actions.
What Is Screen-Level Tokenization?
Review Screen-Level Tokenization, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.

What Is Supervised Delegation? Who Answers for an AI Agent, and What the Record Shows
Explore supervised delegation for AI agents in billing and claims, with named responsibility, tokenization policies and human approvals.

What Is an AI Control Record? The Runtime System of Record for Sensitive AI Work
Explore an AI agent control record for billing and claims, linking permissions, tokenization decisions, approvals and audit evidence.
Book an AI Agent Security Review →
Bring your hardest questions.
Bring one sensitive workflow and the decisions your team needs to keep in its hands.
Book a demoAbout the author

Chris Sowa is a founder of RedactSure and a former CEO of an AI company; he started it years before ChatGPT existed. He previously led AI at Accenture, served as Global VP of Strategy & Innovation at Schneider Electric, was CCO of Sovos, and spent more than a decade at Oracle, with earlier roles at SAP and IBM.