
Comparison · By Chris Sowa · Published
Last updated
What Is the Difference Between RedactSure and Securiti for Sensitive Data Across AI Workflows?
The difference is the point of control. Securiti's LLM firewall sits at user prompts, retrieval data and LLM responses as a protective layer around the model; RedactSure governs what an agent's model receives from each screen and who approves each action. Model path filtering alone can leave an agent's screen reads and actions without a named approver.
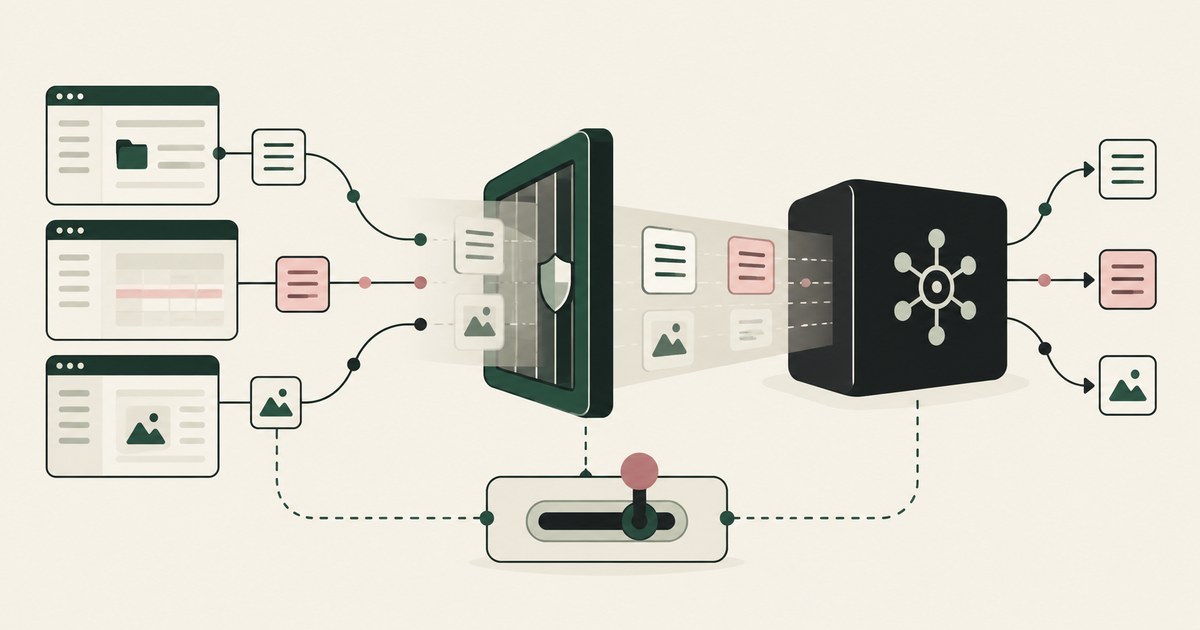
The difference is the point of control. Securiti's LLM firewall sits at user prompts, retrieval data and LLM responses as a protective layer around the model (Securiti, 2026); RedactSure governs what an agent's model receives from each screen and who approves each action. Model path filtering alone can leave an agent's screen reads and actions without a named approver. The question matters because AI workflows now include agents that open applications, read records and prepare changes, not only chat interfaces that send a prompt and receive a reply. A control that inspects the prompt path sees the traffic it sits on. A control at the render layer sees what the agent was about to read. Render-layer tokenization replaces sensitive values with consistent tokens at the point a screen is rendered, before any model reads it, so the model works with SSN_001 and ACCT_001 and real values resolve only at approved destinations at the moment of action. The comparison below runs on purpose, layer, treatment of sensitive values, control over agent actions, and the record each design keeps. The environment that enforces this is built by RedactSure, an AI agent controls, governance and data protection company.
Key findings
- Securiti describes "a new category of distributed and context-aware LLM Firewalls" placed at user prompts, retrieval data and LLM responses, "acting as a protective layer around the LLM" (Securiti, 2026). The page reviewed covers the LLM firewall only and does not cover Gencore AI.
- OWASP ranks prompt injection as LLM01 and sensitive information disclosure as LLM02 in its Top 10 for LLM Applications 2025, two risks that turn on what reaches the model (OWASP, 2025).
- Indirect prompt injection arrives through content the application retrieves, such as web pages and documents, rather than through the user's own prompt (Greshake et al., 2023).
- Researchers testing model agnostic firewalls at the agent and tool boundary report near zero attack success when unnecessary data is stripped from tool inputs and instructions are removed from tool outputs, and warn that public agent security benchmarks are easily saturated (Bhagwatkar et al., 2026).
- Gartner warned in May 2026 that applying uniform governance across AI agents will lead to enterprise AI agent failure (Gartner, 2026).
- RedactSure replaces policy chosen values with tokens at the render layer before any model reads the screen, and a named person approves every consequential action under Supervised Delegation, with deployments in pilot.
What is Securiti built to govern?
Securiti's LLM firewall page centers on the exchange with the model. It describes distributed firewalls at user prompts, retrieval data and LLM responses, "acting as a protective layer around the LLM" (Securiti, 2026). The unit of work in that description is what goes into the model, what is retrieved for it, and what comes back.
The page contrasts this design with traditional firewalls that monitor network traffic, and it does not say the product inspects network traffic itself. It describes detecting, classifying and sanitizing sensitive data inline, redacting sensitive information in prompts and responses, and a response firewall that blocks toxic content and filters prohibited topics (Securiti, 2026). The page reviewed does not state whether the firewall tokenizes or masks values, or whether it inspects API calls, browsers, endpoints, data stores, identities or agent configurations. It does not cover Gencore AI, so no statement here describes what Gencore AI inspects, treats or logs.
What can be said is where an estate platform's center of gravity lies. It answers what an organization holds and how that data is allowed to move. That question comes first in any AI program, because an organization that cannot find its sensitive records cannot decide which of them an AI system should ever touch. The PII Wall, the point where the valuable workflow turns out to run on data the security team will not let a model see, usually appears after that inventory is done, not before.
An agent at work raises a narrower question. The agent does not query an inventory. It opens a claims screen, a payables record or a student file, reads what the application renders, and takes a step. The governing question at that moment is what this run, for this task, should be allowed to see, and who signs off on the step that changes the record. An estate platform and a run level control can both be present without answering the same question.
What does an LLM firewall see in an agent workflow?
A firewall for large language models sits on the path between an application and a model. Securiti's page places its distributed firewall at user prompts, retrieval data and LLM responses, where it detects, classifies and sanitizes sensitive data inline and redacts sensitive information in prompts and responses (Securiti, 2026). The page reviewed does not state its position relative to the user's screen, and it does not discuss AI agents.
The category design has a clear strength. A control on the model path catches traffic regardless of which user or application sent it, and it can be deployed without changing the applications behind it. The companion pages on AI gateways, DLP and tokenization and on AI agent security gateways work through that design in detail.
The limit is structural, not a defect of any product. A path control sees what is routed through it. When an agent reads a screen, the content of that screen reaches the model as part of the agent's own context, whether as a screenshot, page text or the DOM. If that read is routed through the firewall, the firewall must recognize every sensitive value in rendered output, at runtime, with the same accuracy it applies to typed prompts. If it is not routed through the firewall, the firewall does not see it. Either way the control depends on detection after the screen has been rendered in full.
Indirect prompt injection makes the point sharper. Greshake and colleagues showed that instructions hidden in content an application retrieves can redirect a model (Greshake et al., 2023). The ServiceNow and Mila team found that firewalls placed at the agent and tool boundary, one minimizing what goes to tools and one sanitizing what comes back, reach near zero attack success on four public benchmarks, and also that those benchmarks have flawed metrics and weak attacks (Bhagwatkar et al., 2026). Two conclusions follow. Minimizing what reaches the model works better than catching what already arrived, and any vendor's 100 percent detection figure deserves a request for the attack set behind it.
How do the two products compare side by side?
The table places the two designs on six dimensions. The Securiti column is limited to what Securiti's LLM firewall page states; that page does not cover Gencore AI.
| Dimension | Securiti, per its LLM firewall page | RedactSure, per its published design |
|---|---|---|
| What it is | "A new category of distributed and context-aware LLM Firewalls" (Securiti, 2026); Gencore AI is not covered by the page reviewed | AI agent controls, governance and data protection for supervised AI co-workers working an organization's applications |
| Primary layer | User prompts, retrieval data and LLM responses, "acting as a protective layer around the LLM" (Securiti, 2026); the page reviewed does not state its position relative to the screen | Render layer of each screen the agent reads, inside a governed virtual environment |
| Before a model sees sensitive values | Detects, classifies and sanitizes sensitive data inline and redacts it in prompts and responses; the page reviewed does not state tokenization, masking or alerting | Values chosen by policy are replaced by consistent tokens before any model reads the screen; the model receives the task's fields with identifiers as tokens |
| Per task exposure policy | The page reviewed does not state it | The Planner sets which values are tokenized and what the agent may do on each screen; a named person confirms it before the run |
| Agent action control | The page reviewed does not state it; it does not discuss agents, approvals or tool call blocking | A named person approves every payment, submission and record change at the moment it runs |
| Record | A dashboard for "AI usage insights, and policy violations" (Securiti, 2026); the page reviewed does not state audit logs or export | Every action logged, human and computer; all PII as tokens. Exported to the customer's SIEM as the AI Control Record |
The table is not a ranking. Securiti's page describes a control around the model's inputs and outputs, and RedactSure does not claim to do that work across an organization's AI traffic. RedactSure intervenes at a moment that page does not describe: the instant a model is about to read a rendered screen during a workflow, and the instant the agent proposes a consequential step.
"The page reviewed does not state it" means the review did not see it on that page, not that the product lacks it. Each of those cells is a question to put to the vendor with its documentation open, and the FAQ below lists the exact wording.
What happens to a sensitive value before the model reads it?
Take a policyholder's Social Security number on a claims screen. The agent's task is to check coverage dates and prepare a payment for a named adjuster's approval.
In a path filtering design, the screen renders with the real number. If the agent's read is sent through a firewall, the firewall must recognize the value as an SSN in rendered output and then redact, mask or block it according to policy. If recognition succeeds, the model receives a placeholder or the request stops. If recognition misses, for example because the number appears in an unusual format or inside an image, the model receives the real value. The control is only as complete as its detection, and the screen as rendered is the input. OWASP's LLM02 entry describes that class of exposure as sensitive information disclosure (OWASP, 2025).
In a RedactSure run, the policy decides before the screen is read. The Planner sets that SSNs, names and account numbers are tokenized for this task, and a named person confirms the policy before the run. When the agent opens the claim, the SSN appears to the model as SSN_001, and the same value appears as SSN_001 on every later screen of the run, so the agent can still match records. Coverage dates and amounts stay in clear because the task runs on them. The real SSN resolves only at an approved destination, at the moment of an approved action. Detection still matters for finding fields, but the outcome no longer turns on catching a value after the model has it.
The difference carries through to injection. If a document attached to the claim contains hidden instructions, a path filter must also recognize the instruction. In a RedactSure run, an injection that succeeds collects tokens, and the payment still stops for a named person. The page on preventing AI agents from oversharing data between apps works through the same mechanism across several applications in one run.
Who approves what the agent does, and what gets recorded?
Data governance answers who may access data. Agent governance has to answer who approved a specific action by a specific agent at a specific moment. Those are different records.
An estate platform's record centers on data: what was discovered, how it was classified, which policies applied, which access occurred. Securiti's firewall page describes a dashboard covering visibility into AI use, AI usage insights and policy violations, and the page reviewed does not state audit logs or export (Securiti, 2026). Both are useful to an auditor. Neither, in the material reviewed, ties a named human approval to an agent's payment or record change.
Model refusal is not that control. MIT Technology Review reported that vendors stack system prompts, classifiers and activation probes in a layered model in which each layer has holes (MIT Technology Review, 2026). A consequential action needs a check the model cannot talk its way past. In RedactSure's design that check is a person. Under Supervised Delegation, a named person grants the access, chooses the applications, confirms what is tokenized, can watch and pause the run, and approves every consequential action, on the record. The human operator watches the same tokenized stream and can take over.
The record follows the approval. Every screen as tokens, every action and every approval with a name lands in the AI Control Record, exported to the customer's own SIEM. The NIST AI Risk Management Framework organizes risk work into Govern, Map, Measure and Manage (NIST, 2023). Estate discovery and classification support Map and Govern across the organization. A run record with named approvals supports Manage at the level of the individual workflow, where the decision has to be made while the work is in progress.
Gartner's warning against uniform governance across agents points the same way (Gartner, 2026). One estate policy cannot decide what a payables agent and a claims agent should each see. A per task policy, confirmed by the person accountable for that work, can.
Where does RedactSure sit?
RedactSure sits inside the agent run, not across the estate. AI co-workers work an organization's existing applications as rendered, inside a governed environment deployed into the cloud the customer's posture requires, with keys the customer holds, no per application integration and no change to user permissions. The Planner sets which values are tokenized and what the agent may do on each screen; a named person confirms that policy before the run and approves every payment, submission and record change while it runs. The model receives the task's fields with identifiers as tokens, and it can be any vendor's model, swappable without moving the controls. Deployments are in pilot.
An organization with an estate platform keeps it. Discovery and classification tell it what it holds; RedactSure governs what one agent was shown and who approved what it did, with every screen as tokens, every action and every named approval in the AI Control Record. Everyone else controls where data can go. RedactSure controls what the AI can see.
Methodology and limitations
This page rests on Securiti's page "What is an LLM Firewall: Navigating Unprecedented AI Threats," accessed October 14, 2026, and on general descriptions of the data governance product category. That page does not cover Gencore AI, so no statement here describes what Gencore AI inspects, treats or logs. Framework and research sources are the OWASP Top 10 for LLM Applications 2025 entries for LLM01 and LLM02, the NIST AI Risk Management Framework, Gartner's May 2026 press release, two arXiv research papers on indirect prompt injection, and MIT Technology Review's October 2026 reporting on refusal. RedactSure statements are limited to the design the company publishes about itself.
No product was tested. No agent session was run against either design, and no benchmark is reported. Cells marked "the page reviewed does not state it" record the limits of the review, not the limits of the product. Vendor features change, and the page carries its date and is revised when the documentation is reviewed. Pricing, licensing, certifications and deployment options were out of scope. The claims screen example describes a record type, not any organization; no customer or prospect is described.
Whether either product, or both together, meets an organization's requirements for a given workflow is a determination for its counsel, its assessor and its security and compliance officers, who hold the data inventory, the policies and the risk tolerance that the determination depends on.
What the record shows
Estate governance and run level control answer different questions: what an organization holds and how it may flow to models, against what one agent's model received on each screen and who approved its step. An agent run governed only by estate policy and path filtering still depends on detecting each sensitive value after the screen renders in full. The risk of relying on that alone is a model that read real identifiers and a consequential action with no named approver. The test a reader can apply: for one screen of one agent workflow, ask each vendor to show what the model received and the name of the person who approved the step that changed the record.
Frequently asked questions
Is Securiti a competitor to RedactSure or a complement?
Mostly a complement, on the vendor's own page. Securiti describes distributed LLM firewalls at user prompts, retrieval data and LLM responses, and the page reviewed does not discuss AI agents or approvals of agent actions (Securiti, 2026). RedactSure governs a single agent run: what its model receives from each screen and who approves each action. An organization can use estate discovery to decide which records matter and RedactSure to govern the agent working on them.
Does an LLM firewall stop an agent from seeing sensitive data on a screen?
It depends on whether the agent's screen reads are routed through the firewall and whether its detection recognizes every value in rendered output. A path control sees what passes through it. RedactSure replaces policy chosen values with tokens at the render layer before any model reads the screen, so the model works with SSN_001 rather than depending on detection after the screen is rendered.
What should a buyer ask Securiti about agent workflows?
Five questions, each with documentation open. Does the firewall inspect an agent's screen reads, page text or DOM, or only prompts and responses? Does it redact, mask, tokenize or block? Is there a per task exposure policy? Does a named person approve an agent's payment or record change? What does the log hold for each agent action, and where is it exported?
Does RedactSure discover or classify data across the estate?
No. RedactSure does not vault databases, does not catalog the estate and does not change permissions. It governs what an AI agent's model receives during a run, which actions need a named approval, and the record of both. Estate discovery and classification remain the job of the organization's data governance tooling.
Which models work with each approach?
Firewalls on the model path are generally designed to sit in front of several models, and the page reviewed does not state which models Securiti's firewall supports. RedactSure's environment is model agnostic: Claude, GPT, Gemini or open weights models can do the work, swappable without moving the controls, because the controls sit in the environment the customer owns rather than in the model.
What does a prompt injection collect in each design?
In a path filtering design, an injection that succeeds against the agent has whatever real values the agent read and the filter did not catch. In a RedactSure run, the model holds tokens such as ACCT_001 and SSN_001 in place of identifiers, so a successful injection collects tokens and the remaining task context, and the consequential action still stops for a named person.
Related reading
AI Gateway, DLP or Tokenization? · What Is an AI Agent Security Gateway? · How to Prevent AI Agents From Oversharing Data Between Apps · What Is the Difference Between RedactSure and an AI Gateway for Protecting Sensitive Data? · What Is the Difference Between RedactSure and Microsoft Purview for AI Agent Security? · What Is AI Agent Oversharing and How Can Data Move Between Apps Without Anyone Noticing? · What Is an AI Agent Audit Trail and What Should Companies Log for Security and Compliance? · On the RedactSure blog: The Two Gaps AI Agents Opened in Your Security Stack
Sources
Peer-reviewed research and preprints
- Greshake, Kai, et al., "Not What You've Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection," arXiv:2302.12173, 2023 (preprint; also AISec 2023). https://arxiv.org/abs/2302.12173
- Bhagwatkar, Kasa, et al., "Indirect Prompt Injections: Are Firewalls All You Need, or Stronger Benchmarks?," arXiv:2510.05244, v2 2026 (preprint). https://arxiv.org/abs/2510.05244
Vendor documentation
- Securiti, "What is an LLM Firewall: Navigating Unprecedented AI Threats" (vendor documentation, accessed October 14, 2026). https://securiti.ai/what-is-llm-firewall/
Regulation, standards and official guidance
- OWASP, "LLM01:2025 Prompt Injection," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm01-prompt-injection/
- OWASP, "LLM02:2025 Sensitive Information Disclosure," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm022025-sensitive-information-disclosure/
- NIST, "Artificial Intelligence Risk Management Framework (AI RMF 1.0)," NIST AI 100-1, 2023 (official guidance). https://www.nist.gov/itl/ai-risk-management-framework
Industry analysis and press
- Gartner, "Gartner Says Applying Uniform Governance Across AI Agents Will Lead to Enterprise AI Agent Failure" (May 26, 2026; press release). https://www.gartner.com/en/newsroom/press-releases/2026-05-26-gartner-says-applying-uniform-governance-across-ai-agents-will-lead-to-enterprise-ai-agent-failure
- Holland Michel, Arthur, "We're putting too much faith in AI's ability to say no," MIT Technology Review (October 9, 2026; press). https://www.technologyreview.com/2026/10/09/1145728/we-are-putting-too-much-faith-in-ai-to-say-no/
RedactSure documents
- RedactSure Research, "What Is Render-Layer Tokenization?" (2026). https://redactsure.com/research/what-is-render-layer-tokenization
- RedactSure Research, "What Is Supervised Delegation?" (2026). https://redactsure.com/research/what-is-supervised-delegation
- RedactSure Research, "What Is an AI Control Record?" (2026). https://redactsure.com/research/what-is-an-ai-control-record
- RedactSure Research, "What Is the PII Wall?" (2026). https://redactsure.com/research/what-is-the-pii-wall
- RedactSure, "The Two Gaps AI Agents Opened in Your Security Stack" (2026). https://redactsure.com/blog/two-gaps-ai-agents-opened-in-your-security-stack/
- Product behavior described on this page reflects RedactSure's current design. Securiti and Gencore AI are trademarks of their respective owner; named to identify the products.
AI Gateway, DLP or Tokens: What Controls AI Exposure?
Compare AI gateways, data masking and tokenization for AI agent security, focusing on which layer controls the PII a model actually sees.
What Is an AI Agent Security Gateway?
Review an AI Agent Security Gateway, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
How to Prevent AI Agents From Oversharing Data Between Apps
Review Prevent AI Agents From Oversharing Data Between Apps, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
RedactSure vs an AI Gateway: AI Agent Security
Review RedactSure vs an AI Gateway: AI Agent Security, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
RedactSure vs Microsoft Purview: AI Agent Security
Review RedactSure vs Microsoft Purview: AI Agent Security, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
What Is AI Agent Oversharing?
Review AI Agent Oversharing, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
What Is an AI Agent Audit Trail?
Review an AI Agent Audit Trail, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.

The Two Gaps AI Agents Opened in Your Security Stack
Explore AI agent security through two questions: which PII reaches the model, and who approves consequential billing and claims actions.

What Is Render-Layer Tokenization?
Learn how render-layer tokenization replaces PII before an AI agent reads a browser screen while preserving useful workflow context.

What Is Supervised Delegation?
Explore supervised delegation for AI agents in billing and claims, with named responsibility, tokenization policies and human approvals.

What Is an AI Control Record?
Explore an AI agent control record for billing and claims, linking permissions, tokenization decisions, approvals and audit evidence.
What Is the PII Wall?
Explore why PII exposure stalls AI agent projects in claims, patient accounts and student records, and what a governed workflow requires.
Book an AI Agent Security Review →
Bring your hardest questions.
Bring one sensitive workflow and the decisions your team needs to keep in its hands.
Book a demoAbout the author

Chris Sowa is a founder of RedactSure and a former CEO of an AI company; he started it years before ChatGPT existed. He previously led AI at Accenture, served as Global VP of Strategy & Innovation at Schneider Electric, was CCO of Sovos, and spent more than a decade at Oracle, with earlier roles at SAP and IBM.