
Comparison · By Chris Sowa · Published
Last updated
What Is the Difference Between RedactSure and Straiker for Autonomous AI Agent Security?
Straiker and RedactSure act at different points of an autonomous agent's run. Straiker's announcement describes runtime guardrails that detect and block prompt injection, data leakage and tool manipulation. RedactSure decides what the agent's model receives from each screen and who approves each action. Treating them as substitutes leaves unanswered what the model read before anything was blocked.
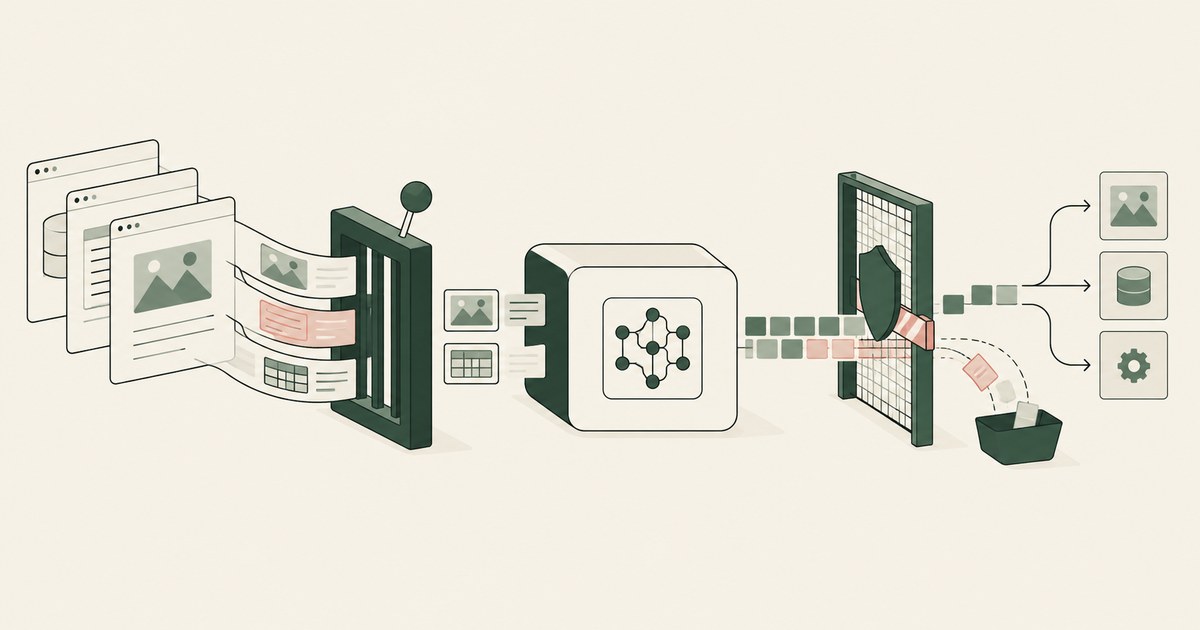
Straiker and RedactSure act at different points of an autonomous agent's run. Straiker's announcement describes runtime guardrails that detect and block prompt injection, data leakage and tool manipulation. RedactSure decides what the agent's model receives from each screen and who approves each action. Treating them as substitutes leaves unanswered what the model read before anything was blocked. An autonomous agent reads application content, calls tools and takes steps without a person typing each instruction, so the security question splits in two: what reaches the model, and what the model is allowed to do with it. Straiker's announcement addresses the second half with detection, blocking and attack testing around the agent (Straiker, vendor announcement, accessed October 14, 2026). RedactSure addresses the first half with render-layer tokenization, which replaces values chosen by policy with consistent tokens before any model reads the screen, and the second half with a named person approving each consequential action. The environment that enforces this is built by RedactSure, an AI agent controls, governance and data protection company.
Key findings
- Straiker describes Defend AI as "runtime security and guardrails that detects and blocks prompt injection, data leakage, and tool manipulation in real time," with guardrails covering prompt injection, toxicity, PII leakage and other agentic threats (Straiker, vendor announcement, accessed October 14, 2026).
- Straiker's Ascend AI attack agents, per the same announcement, autonomously map every prompt, tool call and data flow and provide ongoing assessments and remediation guidance through CI/CD integration, while Chain of Threat Forensics reconstructs every prompt, decision and API call from logs and sensor data (Straiker, vendor announcement, accessed October 14, 2026).
- The announcement does not state whether sensitive data is classified, redacted, masked or tokenized, where Defend AI sits relative to the model or the screen, or any approval step for agent actions (Straiker, vendor announcement, accessed October 14, 2026).
- OWASP ranks prompt injection first in its Top 10 for LLM Applications 2025 and lists sensitive information disclosure second (OWASP, 2025).
- Indirect prompt injection lets instructions hidden in content an application retrieves steer the model that reads it (Greshake et al., 2023).
- Researchers testing firewalls at the agent and tool boundary report about 0 percent attack success on four public benchmarks, and also find those benchmarks have flawed success metrics, implementation bugs and weak attacks (Bhagwatkar et al., 2026).
What does Straiker's announcement say its products do?
Straiker's announcement introduces two products for enterprise agentic AI applications, Ascend AI and Defend AI, together with a capability it calls Chain of Threat Forensics (Straiker, vendor announcement, accessed October 14, 2026). The vendor's one line description of Defend AI is runtime security and guardrails that detect and block prompt injection, data leakage and tool manipulation in real time (Straiker, 2026). Its guardrails, per the announcement, cover prompt injection, toxicity, PII leakage and other agentic threats (Straiker, 2026).
Ascend AI is described as a set of attack agents. The announcement says they autonomously map every prompt, tool call and data flow, and that Ascend AI provides ongoing assessments and remediation guidance through integration with CI/CD pipelines (Straiker, 2026). Together the two products form a test and defend pair: one probes an agentic application for weaknesses before and between releases, and the other watches the application at runtime and blocks the threats it detects.
Chain of Threat Forensics reconstructs every prompt, decision and API call using logs and sensor data, and the announcement says it simplifies audits (Straiker, 2026). A customer quoted in the announcement says the product shows exactly where an incident happened (Straiker, 2026).
The threats the announcement names line up with the first two entries in the OWASP Top 10 for LLM Applications 2025: prompt injection, LLM01, and sensitive information disclosure, LLM02 (OWASP, 2025) (OWASP, 2025).
The announcement is specific on some points and silent on others. It does not state whether Defend AI inspects network traffic, browser sessions, endpoints, data stores, identities or agent configurations. It does not state whether sensitive data is classified, redacted, masked or tokenized; the verbs it uses are detect and block. It mentions automated enforcement in general terms and displays a label reading Agentic Kill Switch, but it does not describe either one, and it does not state any approval step for an agent's actions (Straiker, 2026). Each of those statements describes one dated announcement. Straiker's wider product documentation was not reviewed, and the product may do more than the announcement says.
Where does each design act relative to the model and the screen?
Placement decides what a control can prevent. A guardrail that inspects prompts, responses and tool calls acts on the traffic flowing into and out of the model. A control at the render layer acts before the model receives anything at all. The two placements answer different questions about an autonomous AI agent: the first asks whether a given message or call looks malicious, and the second asks what the model should have been given for the task in the first place.
Straiker's announcement says Defend AI is added with "a few lines of code" and also describes "no code changes or added latency" (Straiker, vendor announcement, accessed October 14, 2026). It does not state where Defend AI sits relative to the model or to a user's screen (Straiker, 2026). What it inspects, per the announcement, is prompts, tool calls and data flows, and what it blocks is prompt injection, data leakage and tool manipulation. The announcement does not say that Defend AI changes what the model receives from an application screen before the model reads it.
RedactSure's design places its first control earlier. AI co-workers work an organization's applications inside a governed environment: a secure virtual machine deployed into the cloud the customer's posture requires, on hardware encrypted enclaves, with keys the customer holds. Every sensitive value chosen by policy, starting with identifiers such as names, SSNs, account numbers and dates of birth, is replaced by a consistent token at the render layer before any model reads the screen. The environment hands the model the task's fields rather than a picture of the screen, so the model works with SSN_001 and ACCT_001. Real values resolve only at approved destinations at the moment of an approved action. There is no per application integration and no change to user permissions.
The difference matters most for indirect prompt injection, in which instructions hidden in content the agent reads redirect it (Greshake et al., 2023). A detector at the model boundary has to recognize the attack to stop it. A render layer control does not depend on recognition: it limits what the attack can reach if a detector misses it. One placement reduces the odds that an attack succeeds; the other reduces what a successful attack is worth.
How do the two compare side by side?
The table places the two designs on eight dimensions. The middle column repeats what the dated announcement states and marks what it does not state. The right column describes RedactSure's published design.
| Dimension | Straiker, per its announcement | RedactSure, per its published design |
|---|---|---|
| What it is | Defend AI runtime guardrails and Ascend AI attack agents for enterprise agentic AI applications (Straiker, vendor announcement, accessed October 14, 2026) | AI agent controls, governance and data protection for AI co-workers working applications inside a governed environment |
| What it inspects | Prompts, tool calls and data flows; network, browser, endpoint, data stores, identities and agent configurations are not stated (Straiker, 2026) | The screens the agent works, at the render layer, inside the governed environment |
| Position relative to model and screen | The announcement does not state it; deployment described as "a few lines of code" (Straiker, 2026) | Before any model reads the screen; the model receives the task's fields with identifiers as tokens |
| Sensitive data | Detects PII leakage and blocks data leakage; classification, redaction, masking and tokenization are not stated (Straiker, 2026) | Values chosen by policy become consistent tokens; real values resolve only at approved destinations at the moment of an approved action |
| Agent actions | Guardrail engine updated in real time to block threats including "tool misuse" and "excessive autonomy"; approvals are not stated (Straiker, 2026) | The Planner sets what the agent may do on each screen; a named person confirms the policy and approves every payment, submission and record change |
| Testing before deployment | Ascend AI attack agents with ongoing assessments and remediation guidance through CI/CD (Straiker, 2026) | No attack agents in the design; the Planner policy is confirmed by a named person before each run |
| Record | Chain of Threat Forensics reconstructs prompts, decisions and API calls from logs and sensor data (Straiker, 2026) | Every action logged, human and computer; all PII as tokens, in the AI Control Record exported to the customer's SIEM |
| Model and keys | The announcement does not state them (Straiker, 2026) | Model agnostic; keys held by the customer |
The table is not a ranking. Straiker's announcement covers attack testing and threat forensics, which RedactSure's design does not claim to provide. RedactSure's design covers what the model receives from each screen and who approves each consequential action, which the announcement does not describe. Where a cell says a point is not stated, the announcement does not state it; that is a statement about one page on one date, not a finding that the capability is absent from the product. A buyer evaluating both should ask Straiker directly about each of those cells and read its current documentation, because a single announcement is written to introduce products, not to specify them.
What happens to sensitive data and to a successful prompt injection in each design?
Take an agent working a customer record that shows a name, an account number and a Social Security number, with a support note on the same screen carrying a hidden instruction to email the record to an outside address. The instruction arrives in content, not in the user's prompt, which is the pattern exercises such as testing prompt injections and manipulations on shopping agents are built to surface.
Under the design Straiker's announcement describes, the guardrail's job is to detect the injection and the attempted leakage and block them (Straiker, vendor announcement, accessed October 14, 2026). If detection succeeds, the email does not go out. The announcement does not state any change to the record's values before the model reads them, so on what is described, protection rests on detecting and blocking the injection and the outbound data (Straiker, 2026).
Detection carries known limits, and the research describes them without singling out any vendor. Bhagwatkar and colleagues report that a Tool-Output Firewall reaches about 0 percent attack success with little utility loss on AgentDojo, Agent Security Bench, InjecAgent and tau-Bench, and in the same paper find that those benchmarks have flawed success metrics, implementation bugs and weak attacks, warning that they are easily saturated (Bhagwatkar et al., 2026). The paper's Tool-Input Firewall strips data not needed for a tool call, which is minimization rather than detection (Bhagwatkar et al., 2026). MIT Technology Review describes the layered defenses vendors stack around models as a Swiss cheese model in which each layer has holes and the hope is that the layers cover each other (MIT Technology Review, 2026).
In a RedactSure run, the Planner policy for the task tokenizes the name, the account number and the Social Security number before the model reads the screen. The model sees ACCT_001 and SSN_001 and the task's other fields. If the hidden instruction succeeds in steering the agent, it collects tokens, and sending anything to an outside address is a consequential action that stops for a named person. Amounts, dates and codes the work runs on stay in clear where the policy says so, so the agent can still do the job.
The two approaches can stack. Detection lowers the chance that an injection steers the agent; tokenization at the render layer limits what a steered agent holds; and named approval stops the consequential step either way. An organization comparing the two is choosing which of those layers it already has, not which single product makes injection impossible.
How are an autonomous agent's actions governed and recorded?
Straiker's announcement describes action governance in terms of blocking. Defend AI automatically updates its guardrail engine in real time to block emerging threats, and the threats it names include tool misuse and excessive autonomy (Straiker, vendor announcement, accessed October 14, 2026). The announcement refers to automated enforcement in general terms and shows an Agentic Kill Switch label without describing it. It does not state policies that define what an agent may do, approval steps, or who approves (Straiker, 2026).
RedactSure governs action through Supervised Delegation: a named person grants the access, chooses the applications, confirms what is tokenized, can watch and pause the run, and approves every consequential action, on the record. The Planner sets what the agent may do on each screen, and that policy is confirmed by a named person before the run. The AI never pays, submits or changes a record by itself. Each payment, submission and record change waits for a named person, and the human operator can watch, pause and take over the same tokenized stream.
The distinction tracks an argument MIT Technology Review makes about model refusal: a model declining a request is treated as a primary safety mechanism, yet refusal is far from foolproof (MIT Technology Review, 2026). A consequential action benefits from a control the model cannot talk its way past, and a person's approval is outside the model by construction.
The records answer different questions too. Chain of Threat Forensics reconstructs every prompt, decision and API call using logs and sensor data and is said to simplify audits (Straiker, 2026); report formats and dashboards are not stated. Its question is what happened in an incident. RedactSure's AI Control Record holds every screen the agent saw as tokens, every action and every approval with a name, exported to the customer's own SIEM. Its question is, for this run, what the model received and who approved each step. The checks an auditor runs against that record are set out in how to audit AI agent activity. The NIST AI Risk Management Framework places this work under Manage, alongside Govern, Map and Measure (NIST, 2023): a forensic reconstruction supports learning after the fact, and a named approval supports a decision while the work is in progress.
Where does RedactSure sit?
For the autonomous agent run itself, RedactSure governs what the model receives and who approves what it does. Values chosen by policy are replaced by consistent tokens at the render layer before any model reads the screen, the model receives the task's fields with identifiers as tokens, and real values resolve only at approved destinations at the moment of an approved action. The Planner sets the policy and a named person confirms it; under Supervised Delegation a named person approves every payment, submission and record change. Every screen as tokens, every action and every approval lands in the AI Control Record, exported to the customer's SIEM, with keys the customer holds. The environment is model agnostic, needs no per application integration and changes no user permissions. Deployments are in pilot. Runtime threat detection and attack testing of the kind Straiker announces can sit alongside it. Everyone else controls where data can go. RedactSure controls what the AI can see.
Methodology and limitations
This page rests on one vendor announcement from Straiker, accessed October 14, 2026 and cited as a vendor announcement, and on sources read as of October 13, 2026: the OWASP Top 10 for LLM Applications 2025 entries for LLM01 and LLM02 and the NIST AI Risk Management Framework as standards and official guidance; Greshake and colleagues and Bhagwatkar and colleagues as peer-reviewed research and preprints; and MIT Technology Review as press. RedactSure statements are limited to the design facts the company publishes about itself.
No product was tested. No Straiker or RedactSure session was run, and no comparative benchmark is reported. Straiker's product documentation beyond the announcement was not reviewed, so every statement that a point is not stated refers to that announcement on that date and not to the product as a whole. Vendor features change; the page carries its date and is revised when the documentation changes. Pricing, deployment requirements and regional availability were out of scope. The customer record and support note example describes a record type and an attack pattern, not any organization; no customer or prospect is described.
Whether either product, or the two together, meets an organization's requirements for a given agent workflow is a determination for its counsel, its assessor and its security and compliance officers, who hold the policies, the data inventory and the risk tolerance that the determination depends on.
What the record shows
The announcement reviewed describes detection, blocking, attack testing and forensic reconstruction around an agentic application. The other design decides what the model receives from each screen and requires a named person's approval for every consequential action. An agent protected only by detection still reads whatever the screen shows, so a missed injection reaches real values. The test: for one screen of one run, show what the model received and who approved the step that changed a record.
Frequently asked questions
Does Straiker change what the model sees before it reads a screen?
The announcement reviewed does not say so. It describes detecting and blocking prompt injection, data leakage and tool manipulation. It does not state tokenization or masking, or where Defend AI sits relative to the model or the screen. Buyers who need that answer should ask Straiker and read its current documentation.
Does RedactSure detect prompt injection?
RedactSure's design does not rest on detection. It limits what an injection can reach: identifiers become tokens such as SSN_001 and ACCT_001 before the model reads the screen, and every consequential action waits for a named person. A successful injection collects tokens, and its attempted action stops for approval.
Can Straiker and RedactSure run in the same organization?
Yes. They act at different points. Straiker's announced guardrails inspect prompts, tool calls and data flows and block detected threats. RedactSure governs a single agent run: what the model receives from each screen and who approves each consequential action. Detection lowers the odds of a successful attack; tokenization limits what a successful one holds.
Who approves an autonomous agent's actions in each design?
Straiker's announcement describes blocking threats such as tool misuse and excessive autonomy but does not state an approval step or who approves. In RedactSure's design, a named person confirms the Planner policy before the run and approves every payment, submission and record change while it runs.
What does each product record for an audit?
Chain of Threat Forensics, per the announcement, reconstructs every prompt, decision and API call from logs and sensor data. RedactSure's AI Control Record holds every screen the agent saw as tokens, every action and every approval with a name, exported to the customer's SIEM. One reconstructs an incident; the other records each run.
Does RedactSure test agents before deployment the way Ascend AI does?
No. Ascend AI, per Straiker's announcement, uses attack agents and gives ongoing assessments through CI/CD. RedactSure's design does not include attack agents. Its pre run control is the Planner policy a named person confirms before the agent starts, setting what is tokenized and what the agent may do on each screen.
Related reading
What Is an Autonomous AI Agent and How Do You Secure One That Acts Without Human Approval? · How to Test Prompt Injections and Manipulations on Shopping Agents · How Do You Audit AI Agent Activity? · What Is AI Agent Runtime Security and What Happens After an Agent Gets Access? · What Is the Difference Between RedactSure and Palo Alto Networks Prisma AIRS for AI Agent Runtime Security? · On the RedactSure blog: The Two Gaps AI Agents Opened in Your Security Stack
Sources
Peer-reviewed research and preprints
- Greshake, Kai, et al., "Not What You've Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection," arXiv:2302.12173, 2023 (preprint; also AISec 2023). https://arxiv.org/abs/2302.12173
- Bhagwatkar, Kasa, et al., "Indirect Prompt Injections: Are Firewalls All You Need, or Stronger Benchmarks?," arXiv:2510.05244, v2 March 2026 (preprint). https://arxiv.org/abs/2510.05244
Vendor documentation
- Straiker, "Industry-First Agentic AI Security Solutions" (accessed October 14, 2026; vendor announcement). https://www.straiker.ai/blog/straiker-introduces-industrys-first-attack-and-defense-agents-to-secure-enterprise-agentic-ai-applications
Regulation, standards and official guidance
- OWASP, "LLM01:2025 Prompt Injection," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm01-prompt-injection/
- OWASP, "LLM02:2025 Sensitive Information Disclosure," Top 10 for LLM Applications 2025 (standard). https://genai.owasp.org/llmrisk/llm022025-sensitive-information-disclosure/
- NIST, "Artificial Intelligence Risk Management Framework (AI RMF 1.0)," NIST AI 100-1, 2023 (official guidance). https://www.nist.gov/itl/ai-risk-management-framework
Industry analysis and press
- Holland Michel, Arthur, "We're putting too much faith in AI's ability to say no," MIT Technology Review, October 9, 2026 (press). https://www.technologyreview.com/2026/10/09/1145728/we-are-putting-too-much-faith-in-ai-to-say-no/
RedactSure documents
- RedactSure Research, "What Is Render-Layer Tokenization?" (2026). https://redactsure.com/research/what-is-render-layer-tokenization
- RedactSure Research, "What Is Supervised Delegation?" (2026). https://redactsure.com/research/what-is-supervised-delegation
- RedactSure Research, "What Is an AI Control Record?" (2026). https://redactsure.com/research/what-is-an-ai-control-record
- RedactSure Research, "How to Test Prompt Injections and Manipulations on Shopping Agents" (2026). https://redactsure.com/research/how-to-test-prompt-injections-and-manipulations-on-shopping-agents
- RedactSure, "The Two Gaps AI Agents Opened in Your Security Stack" (2026). https://redactsure.com/blog/two-gaps-ai-agents-opened-in-your-security-stack/
- Product behavior described on this page reflects RedactSure's current design. Straiker, Ascend AI, Defend AI and Chain of Threat Forensics are trademarks of their respective owner; named to identify the products.
What Is an Autonomous AI Agent?
Review an Autonomous AI Agent, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
How to Test Prompt Injection Against Shopping Agents?
Review Test Prompt Injection Against Shopping Agents, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
How Do You Audit What an AI Agent Saw and Did?
Explore AI agent audit evidence for sensitive claims and billing, including tokenization policies, approvals and logs that avoid raw PII.
What Is AI Agent Runtime Security?
Review AI Agent Runtime Security, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.
RedactSure vs Prisma AIRS: AI Agent Security
Review RedactSure vs Prisma AIRS: AI Agent Security, with AI agent security, tokenization and approval checks for sensitive enterprise workflows.

The Two Gaps AI Agents Opened in Your Security Stack
Explore AI agent security through two questions: which PII reaches the model, and who approves consequential billing and claims actions.

What Is Render-Layer Tokenization?
Learn how render-layer tokenization replaces PII before an AI agent reads a browser screen while preserving useful workflow context.

What Is Supervised Delegation?
Explore supervised delegation for AI agents in billing and claims, with named responsibility, tokenization policies and human approvals.

What Is an AI Control Record?
Explore an AI agent control record for billing and claims, linking permissions, tokenization decisions, approvals and audit evidence.
Book an AI Agent Security Review →
Bring your hardest questions.
Bring one sensitive workflow and the decisions your team needs to keep in its hands.
Book a demoAbout the author

Chris Sowa is a founder of RedactSure and a former CEO of an AI company; he started it years before ChatGPT existed. He previously led AI at Accenture, served as Global VP of Strategy & Innovation at Schneider Electric, was CCO of Sovos, and spent more than a decade at Oracle, with earlier roles at SAP and IBM.